













IT asset discovery is a process organizations use to identify, catalog, and document all their IT assets. By keeping an accurate inventory of every technology resource that adds value to the business, teams can ensure visibility, control, and compliance.
As cloud adoption and remote work expand, IT asset discovery has become a core IT Asset Management (ITAM) practice. Along with financial tracking, it now supports cybersecurity, reduces blind spots, and helps meet regulatory requirements. This is why discovery has to run continuously: dynamic environments require a dynamic approach.
In this article, we’ll explore key approaches and best practices for achieving continuous IT asset discovery.
Updated: November 2026
IT asset discovery is the process organizations use to identify, classify, and document their technology assets within a centralized system. This includes hardware, software, SaaS applications, cloud resources, and any other IT asset that delivers value to the business.
The primary goal of IT asset discovery is to provide complete visibility into the IT environment while keeping asset data accurate as the environment evolves. Because modern infrastructures constantly change, discovery has two jobs: knowing what exists and making sure every change is reflected continuously.
There are multiple ways to approach IT asset discovery, and the right method always depends on the organization’s technical landscape, operational needs, and available resources. In the following sections, we’ll explore the most common approaches and how they work together. If you are already choosing software for the job, the main asset discovery tools differ mostly in how they combine these approaches.
There are two main approaches to IT asset discovery: agent-based and agentless. Both aim to provide visibility across your organization’s IT environment, but they do it in different ways.
While agent-based discovery offers deeper, continuous insight into devices and services, agentless discovery enables fast coverage without installation requirements. In most cases, organizations combine both methods to achieve a balanced, accurate view of their assets.
Agent-based discovery relies on lightweight software agents installed on each device. These agents collect detailed data about hardware, software, configurations, and running services, then send it back to the ITAM platform.
Agent-based discovery pros:
Agent-based discovery cons:
Agent-based discovery is best suited for environments that prioritize data accuracy, ongoing monitoring, and control, such as hybrid workplaces or highly regulated industries.
Agent-based discovery is ideal when organizations need deep, continuously updated asset intelligence. It becomes especially valuable in environments where devices frequently change state, location, or configuration.
You should typically prioritize agent-based discovery when:
Agentless discovery (also known as network scanning) detects assets across the network without installing software on each device. It uses protocols like SNMP, WMI, SSH, or API calls to collect information remotely.
Agentless discovery pros:
Agentless discovery cons:
Agentless discovery is often chosen for organizations that need broad visibility with minimal setup, especially in stable, on-premises environments.
Agentless discovery is most effective when speed of deployment and broad network visibility are more important than highly granular endpoint data. It works well in environments with stable, well-defined network boundaries.
Agentless discovery is usually a strong choice when:
In practice, most organizations adopt a hybrid discovery strategy. They use agent-based discovery for critical endpoints and mobile assets, while agentless scanning covers servers, network devices, and other connected equipment.
This combined approach offers the best of both worlds: continuous visibility, minimal blind spots, and flexibility to adapt to different infrastructure types.
Common scenarios where a hybrid approach works particularly well include:
IT asset discovery can run continuously or through periodic scans. The difference lies in how often and automatically assets are updated.
Continuous discovery keeps records current as changes happen. It relies on agents, integrations, and update triggers, which are automatic events that refresh asset data when something changes, such as a new device joining the network or a software update being installed.
For discovery to be truly continuous, organizations typically need:
Periodic scans happen at fixed intervals, like daily or weekly. They’re easier to manage but may miss short-term changes in fast-moving environments.
Most organizations combine both, using continuous discovery to keep records up to date and periodic scans for scheduled validation.
Once assets are discovered, the next step is ensuring the data is consistent and reliable. This is where data standardization and data normalization become essential. Standardization defines how asset data should be structured, while normalization applies those rules to eliminate variations and inconsistencies.
In practice, normalization unifies equivalent values. For example, “Dell Inc.”, “DELL”, and “Dell Technologies” are consolidated under a single manufacturer name, preventing fragmented or misleading records.
Many ITAM frameworks also reference reconciliation, sometimes as a separate step and sometimes as part of normalization. While normalization focuses on data consistency, reconciliation resolves asset identity, determining whether multiple records represent the same asset and preventing duplicates.
Modern ITAM platforms typically automate these processes using catalogs, matching rules, and correlation logic, transforming raw discovery data into a trustworthy inventory. The result is the foundation of your IT asset inventory, the record every other ITAM process reads from.
Databases are some of the most valuable assets in any environment, and some of the least visible. They run inside servers and virtual machines, so a scan that registers the host often stops there, and the engines, versions, and instances on top of it never reach the inventory. Test instances and forgotten development databases are the usual blind spots, and they are also the ones most likely to run unsupported versions.
For each database, the inventory should record at least four data points: the engine, its version, the server where it runs, and its End-of-Support date. With those fields in place, IT can see which versions are out of support, plan upgrades before an audit asks about them, and know which server a migration will affect. Ownership, dependencies, and change evidence complete the picture, and they are the core of database governance.
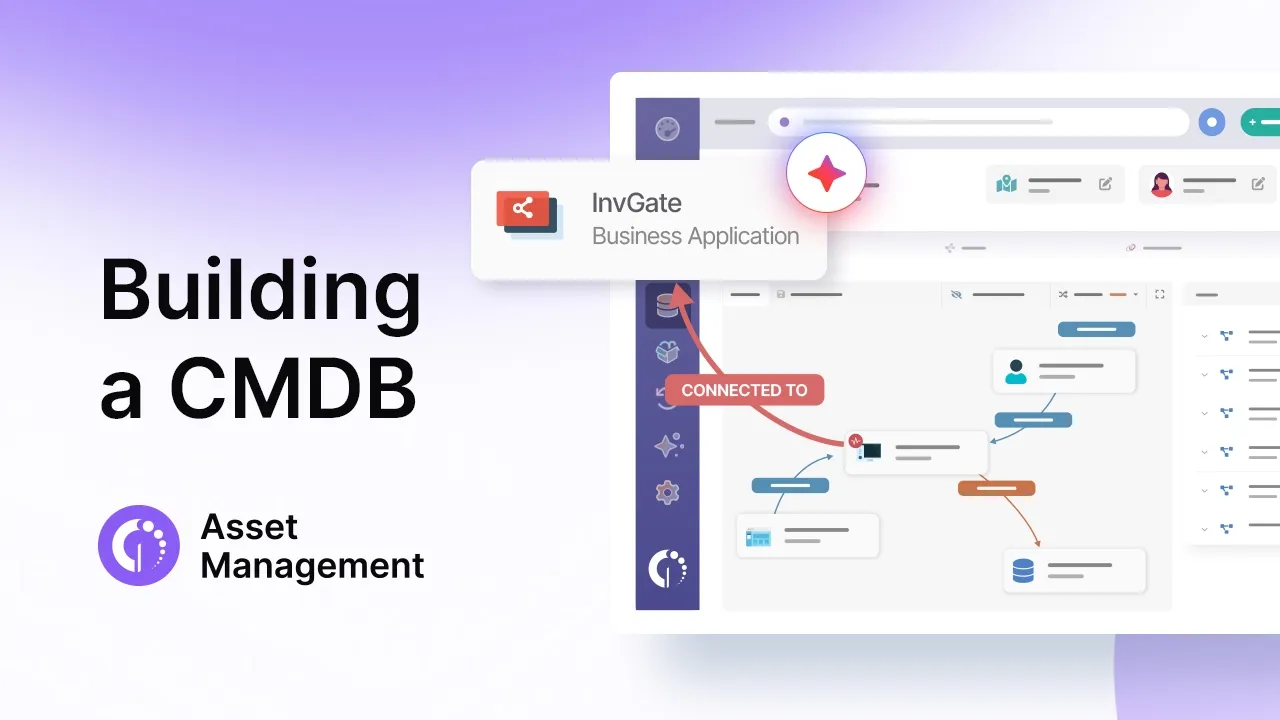
Integrating IT asset discovery and inventory data with a Configuration Management Database (CMDB) is an important step for organizations seeking greater visibility of their IT environment or tighter control over service dependencies and changes.
This connection creates a reliable source of truth that links assets to the services they support, improving impact analysis, incident resolution, and overall data consistency. Every asset should also be connected to the services it supports and the people responsible for it, so an impact analysis always ends with an owner who can act.
In practice, this relationship often follows a simple model: a hardware or software asset supports an application, which in turn enables a business service. For example, a server hosts a CRM application, and that application supports the sales service.
A practical starting point for CMDB integration is focusing on business-critical services. Mapping dependencies for high-impact services first helps organizations deliver immediate operational value while progressively expanding CMDB coverage.
SaaS discovery is a key part of IT asset discovery that focuses on identifying all cloud-based applications used within an organization (both approved and unapproved). This practice helps uncover and control shadow IT, reducing security and compliance risks.
Modern solutions use Identity Providers (IdP), Single Sign-On (SSO) integrations, Cloud Access Security Brokers (CASB), and API connections to SaaS platforms to detect usage and collect metadata. Some organizations also rely on spend analysis or internal surveys to reveal hidden subscriptions and user activity.
By combining these methods, IT teams can uncover blind spots, protect sensitive data, and optimize SaaS spending, so every cloud application is accounted for and securely managed.
Tracking the right metrics helps demonstrate the impact of your IT asset discovery and inventory efforts. These indicators show how complete, current, and reliable your asset data really is.
Together, these metrics highlight the value of maintaining a complete, accurate, and continuously updated asset inventory.
Even with the right tools, IT asset discovery can fall short if the process isn’t consistent or well managed. Here are some common mistakes organizations make and how to avoid them.
InvGate Asset Management is ITAM software that offers an enterprise experience without the complexity or the price of one, built around ease of use: an intuitive interface, a no-code approach, and fast deployment. It runs in the cloud or on-premises, including air-gapped environments, with the same capabilities in both, and its security program includes SOC 2 Type II and ISO 27001:2022 certifications.
Discovery in InvGate Asset Management combines four methods, so each type of asset is captured by the one that fits it best. Together they feed a single inventory of hardware, software, cloud resources, and non-IT assets:
Once assets reach the inventory, InvGate Asset Management keeps adding context to each record. That context is what turns discovery data into decisions:
A practical approach to implementing automated discovery with InvGate Asset Management typically follows a simple sequence:
Dia Argentina, a convenience supermarket chain with more than 1,000 stores across seven provinces, couldn’t answer basic questions about its equipment: how much stock it had, where it was, and in what condition. Audits required up to 20 days of manual work.
The company built its inventory from scratch in InvGate Asset Management, combining agents, the VMware integration, SNMP, and manual uploads. According to the Dia Argentina case study, it now has 28,000+ inventoried assets with 100% visibility, and audits moved from 20 days of manual work to immediate reports, recovering 160 hours per audit.
IT asset discovery works when it runs continuously, combines agent-based and agentless methods, and feeds a normalized inventory connected to the services it supports. Databases, SaaS applications, and remote devices are where most inventories fall short, so they deserve a place in the scope from day one.
InvGate Asset Management brings the four discovery methods, lifecycle data, and relationships into one inventory. Start a free 30-day trial to see your own environment in it, or talk to Sales to plan discovery across your networks.
These are the questions IT teams ask most often when they set up asset discovery. Each answer summarizes what the sections above cover.
Asset discovery is the process that finds assets and collects their data. The asset inventory is the record that stores that data, keeps it normalized, and connects it to owners, contracts, and lifecycle dates.
At minimum: name, serial number, MAC address, hardware specs, installed software and versions, network details, location, and assigned user. For servers, add the databases and services running on them.
Network and agent-based discovery can’t detect assets without an IP address, such as monitors, docking stations, or furniture. Those assets are registered manually or by CSV and tracked with QR codes or RFID tags.

